01
AI Agent Spend Governance and Cost Optimization
AI agents are now doing real work inside Pakistani marketing teams — drafting content, scoring leads, answering WhatsApp messages, optimizing ad copy, and enriching CRM records. The same shift that made AI marketing agents and AI sales agents affordable to build has created a second, quieter problem: every successful agent keeps spending money long after launch. Token usage compounds with adoption, model providers bill in USD, and most teams have no reliable way to see which agent, workflow, or campaign actually drove the charge. WeProms Digital sets up the governance layer — budgets, routing, caching, monitoring, and audit trails — that keeps your agents cost-accountable in PKR or USD instead of letting them turn into an open-ended monthly bill.
02
Why This Service Exists
An agent that works is an agent that gets used, and an agent that gets used is an agent that spends. The first month after launch usually looks cheap, because usage is low and the team is still testing. By the third or fourth month, the same agents are running across more campaigns, more team members are triggering them, and the provider bill has quietly doubled or tripled. None of it is waste in the obvious sense — the agents are doing genuinely useful work — but there is no structure in place to say how much each piece of work should cost, which model it should run on, or whether the outcome justified the spend.
This is the gap governance fills. Treating agent spend as a managed cost center — the way mature teams already treat cloud or ad spend — turns a source of anxiety into a source of leverage. You can keep deploying agents aggressively when you know each one carries a ceiling, a routing policy, and a cost-per-outcome attached to it, rather than hoping the next invoice stays manageable.
03
Where AI Agent Costs Quietly Leak
Most overspend on AI agents comes from a handful of recurring patterns, and almost all of them stay invisible until someone actually audits the usage data. The most common is frontier models used for routine work. Classification, tagging, summarization, and metadata generation get sent to the most expensive model in the stack when a cheap, fast model would do the same job for a fraction of the price. Because the calls succeed and the output looks fine, nobody notices — until the bill arrives.
The second leak is context bloat. Agents that re-inject entire brand manuals, full campaign histories, or raw analytics exports into every single call burn tokens on material that rarely changes. Multiply that across thousands of runs and the same instructions get paid for over and over again. The third is runaway loops: a multi-step agent that retries a failing tool, re-plans a campaign, or generates endless creative variants without a stop condition can consume a week of budget in a single afternoon, and often does it overnight when no one is watching.
Underneath all of this is usually no per-agent or per-campaign visibility. The provider dashboard shows aggregate tokens and dollars, but not which workflow, which team, or which outcome is responsible. Without that breakdown, low-ROI agents keep running simply because nobody can see they are underperforming, and duplicate agents multiply across teams because nobody realizes a similar one already exists.
04
How WeProms Puts Guardrails Around Agent Spend
WeProms installs a gateway and observability layer between your agents and their model providers, so calls are routed, capped, cached, and logged in one governed place rather than scattered across individual tools. The first lever is tiered model routing. Routine tasks like tagging and summarization move to inexpensive models, while genuinely hard work — strategy, complex creative direction, cross-channel orchestration — is the only thing that touches frontier pricing. Fallback chains keep agents resilient if a provider is slow, rate-limited, or down.
The second lever is caching. Stable system prompts, brand guidelines, and persona definitions get prompt-cached at the provider level, and repetitive requests get caught by a semantic cache so the same intelligence is never paid for twice. For marketing workloads, where prompts are highly repetitive, this is usually the single largest saving. The third lever is budgets and limits — per-agent and per-workflow token and dollar caps, rate limits on bulk jobs, and iteration caps that kill runaway loops before they do real damage.
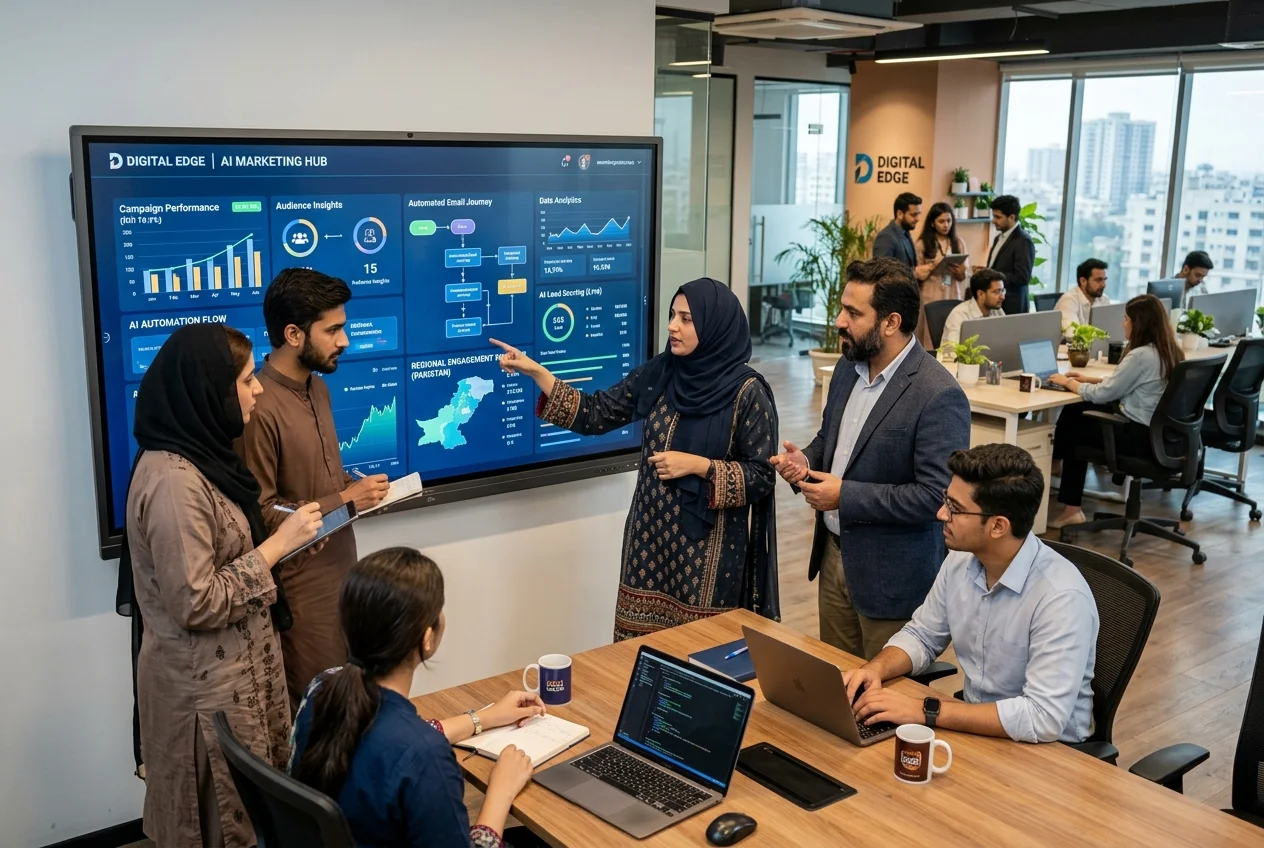
The final piece is measurement. Every call is tagged with agent, workflow, campaign, and team, so spend rolls up into a dashboard you can actually read. We add anomaly alerts that flag unusual spikes within hours instead of at month-end, and we tie cost back to outcomes — cost per asset, per lead, per conversion — so you can see which agents earn their keep and which need to be reined in or retired.
05
What Changes Once Spend Is Governed
The immediate change is predictability. A monthly AI bill that used to swing wildly starts to behave, because hard caps prevent any single agent from blowing past its share and routing pulls routine work off the most expensive models. Finance stops being ambushed by USD invoices that move with the rupee, because budgets and forecasts are set explicitly rather than discovered after the fact.
The longer-term change is decision quality. When you can see the cost per outcome for each agent, budgeting becomes a matter of following results — investing more in agents that produce cheap, high-quality outcomes and constraining the ones that do not. That is the difference between AI as a mysterious expense and AI as a measurable, governable part of the marketing system. It is also what makes agent deployments sustainable for Pakistani SMEs operating in PKR: the work stays affordable to keep running, not just affordable to launch.
06
The Delivery Path
We start with an audit of every connected agent, model, provider key, and workflow, mapping current spend against actual usage so we can see where the money is going and where the biggest leaks sit. From there we design the governance policy — a tiered routing map, per-workflow budget caps, caching rules, rate limits, and the ROI tags each agent will carry.
Next we stand up the gateway and observability layer, configuring the routing, caching, logging, and alerting tools that fit your stack, and migrate agent calls through the governed route with fallback chains in place so nothing breaks during cutover. Finally, we report on cost-per-outcome and tune the routing and caching against real usage data, because governance is an ongoing practice rather than a one-time cost cut. The deliverable is a system your team can trust to scale without the bill scaling unpredictably alongside it.
07
Who This Service Is For
This service is built for teams that have already deployed AI agents — across marketing, sales, content, lifecycle, or analytics — and are now watching the provider bill climb without a clear way to control it. It fits B2B SaaS companies, ecommerce brands, and service businesses in Lahore, Karachi, and Islamabad whose agents bill in USD, as well as international teams that want a Pakistan-based partner to install the governance layer. If you have working agents but no budgets, no routing, and no per-outcome visibility, this is the engagement that turns those agents from a cost risk into a governed, ROI-accountable asset.